A Hybrid Vision Transformer–Graph Neural Network Framework for High-Resolution Surveillance Scene Understanding
DOI:
https://doi.org/10.12928/biste.v8i5.16148Keywords:
Vision Transformer, Graph Neural Network, Attention Mechanism, Multi-modal Feature Fusion, Relational Scene Understanding, UA-DETRAC DatasetAbstract
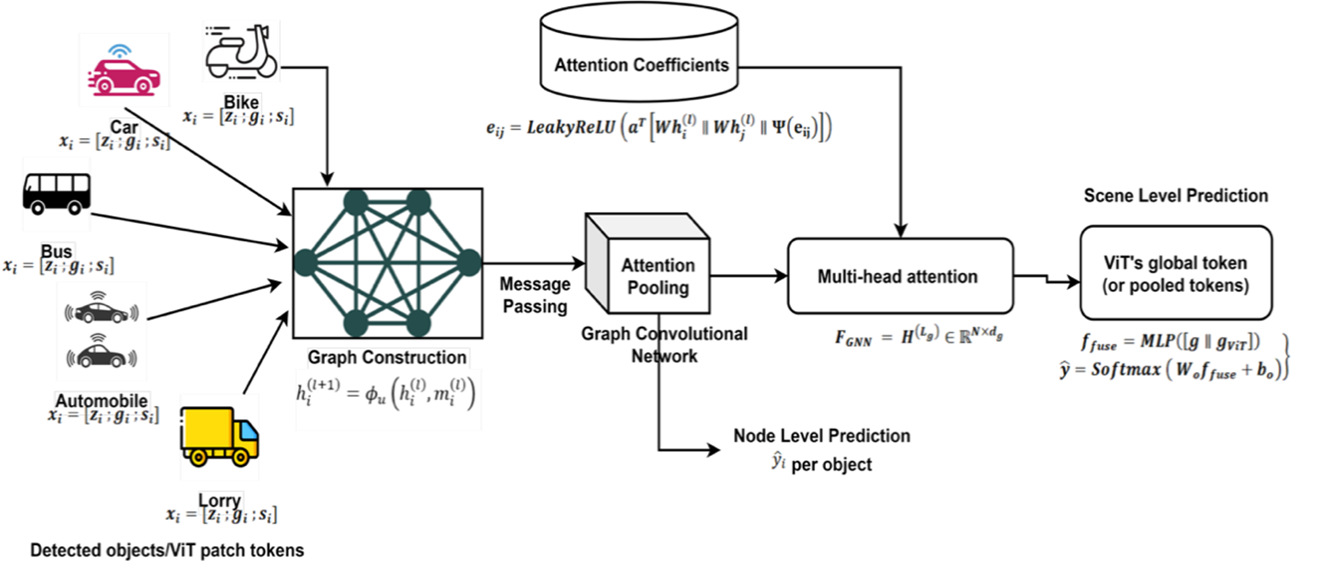
Real-time processing and accuracy of surveillance systems in a real-world environment are very critical to the understanding of the scene. Current deep learning methods, however, have failed to sufficiently learn the global context and relations between objects from high resolution surveillance information. In this study, a hybrid deep learning framework is proposed, which incorporates the merits of Vision Transformers, Graph Neural Networks, and attention-based fusion to tackle these challenges. The novelty of the research is that they design a single architecture combining global features extraction, and relational reasoning to better interpret the surveillance scene. The proposed model has an improved representation of features, which includes complementary mechanisms in a single model. In terms of method, Vision Transformers are used to use global spatial features from surveillance frames. Relationships between the detected objects are described in a structured graph using the Graph Neural Networks. In complex scenes, these features are adaptively integrated together through an attention guided fusion scheme, which improves the classification and understanding of complex scenes. Experimental results on UA-DETRAC dataset show that the proposed framework achieves higher accuracy, precision, recall, F1 score, mAP and AUC (0.962%, 0.955%, 0.958%, 0.956%, 0.960% and 0.97 respectively). Furthermore, the model's performance is 78 fps making it a compatible model for real-time surveillance systems. Analysis of these results shows that the method is robust and improved consistently compared with the baseline methods in all performance measure. Last but not least, the proposed framework is very efficient and accurate, and is able to achieve a good balance between accuracy and computation efficiency in real-time intelligent surveillance. The results prove its potential application for surveillance, traffic monitoring and security critical environments in smart cities.
References
M. A. Goffer, M. S. Uddin, S. N. Hasan, C. R. Barikdar, J. Hassan, N. Das, and R. Hasan, "AI-enhanced cyber threat detection and response advancing national security in critical infrastructure," J. Posthumanism, vol. 5, no. 3, pp. 1667–1689, 2025, https://doi.org/10.63332/joph.v5i3.965.
T. Turay and T. Vladimirova, "Toward performing image classification and object detection with convolutional neural networks in autonomous driving systems: A survey," IEEE Access, vol. 10, pp. 14076–14119, 2022, https://doi.org/10.1109/ACCESS.2022.3147495.
A. Dede, H. Nunoo-Mensah, E. T. Tchao, A. S. Agbemenu, P. E. Adjei, F. A. Acheampong, and J. J. Kponyo, "Deep learning for efficient high-resolution image processing: A systematic review," Intell. Syst. Appl., vol. 25, p. 200505, 2025, https://doi.org/10.1016/j.iswa.2025.200505.
M. Trigka and E. Dritsas, "A comprehensive survey of deep learning approaches in image processing," Sensors, vol. 25, no. 2, p. 531, 2025, https://doi.org/10.3390/s25020531.
M. A. Rasool, S. Ahmad, S. Mardieva, S. Akter, and T. K. Whangbo, "A comprehensive survey on real-time image super-resolution for IoT and delay-sensitive applications," Appl. Sci., vol. 15, no. 1, p. 274, 2024, https://doi.org/10.3390/app15010274.
J. Hu, Z. Qi, J. Wei, J. Chen, R. Bao and X. Qiu, "Few-Shot Learning with Adaptive Weight Masking in Conditional GANs," 2024 International Conference on Electronics and Devices, Computational Science (ICEDCS), pp. 435-439, 2024, https://doi.org/10.1109/ICEDCS64328.2024.00083.
M. Khan, J. Ahmad, A. El Saddik, W. Gueaieb, G. De Masi, and F. Karray, "Drone-HAT: Hybrid attention transformer for complex action recognition in drone surveillance videos," in Proc. IEEE/CVF Conf. Comput. Vis. Pattern Recognit. (CVPR), pp. 4713–4722, 2024, https://doi.org/10.1109/CVPR.2024.00471.
M. Khalil, A. Khalil, and A. Ngom, "A comprehensive study of vision transformers in image classification tasks," arXiv preprint arXiv:2312.01232, 2023, https://doi.org/10.48550/arXiv.2312.01232.
C. J. Swinney and J. C. Woods, "A review of security incidents and defence techniques relating to the malicious use of small unmanned aerial systems," IEEE Aerosp. Electron. Syst. Mag., vol. 37, no. 5, pp. 14–28, 2022, https://doi.org/10.1109/MAES.2022.3151308.
D. Kumari, A. Suhag, and B. Kaur, "Advancements in intelligent video surveillance for public safety: A comprehensive review," Int. J. Res. Appl. Sci. Eng. Technol., vol. 12, no. 5, pp. 1761–1770, 2024, https://doi.org/10.22214/IJRASET.2024.61041.
J. H. Nderitu, "Mental state adaptive interfaces as a remedy to the issue of long-term continuous human-machine interaction," J. Robot. Spectr., vol. 1, pp. 78–89, 2023, https://doi.org/10.53759/9852/JRS202301008.
H. Shi, L. Fang, X. Chen, C. Gu, K. Ma, X. Zhang, and E. G. Lim, "Review of the opportunities and challenges to accelerate mass-scale application of smart grids with large-language models," IET Smart Grid, vol. 7, no. 6, pp. 737–759, 2024, https://doi.org/10.1049/stg2.12191.
A. L. C. Ottoni, R. M. de Amorim, M. S. Novo, and D. B. Costa, "Tuning of data augmentation hyperparameters in deep learning to building construction image classification with small datasets," Int. J. Mach. Learn. Cybern., vol. 14, no. 1, pp. 171–186, 2023, https://doi.org/10.1007/s13042-022-01555-1.
P. Br and N. Rajkumar, "Real-time intelligent video surveillance system using recurrent neural network," Procedia Comput. Sci., vol. 235, pp. 1522–1531, 2024, https://doi.org/10.1016/j.procs.2024.04.143.
S. Natha, F. Ahmed, M. Siraj, M. Lagari, M. Altamimi, and A. A. Chandio, "Deep BiLSTM attention model for spatial and temporal anomaly detection in video surveillance," Sensors, vol. 25, no. 1, p. 251, 2025, https://doi.org/10.3390/s25010251.
P. Zhang, X. Dai, J. Yang, B. Xiao, L. Yuan, L. Zhang, and J. Gao, "Multi-scale vision longformer: A new vision transformer for high-resolution image encoding," in Proc. IEEE/CVF Int. Conf. Comput. Vis. (ICCV), pp. 2998–3008, 2021, https://doi.org/10.48550/arXiv.2103.15358.
V. Hassija, B. Palanisamy, A. Chatterjee, A. Mandal, D. Chakraborty, A. Pandey, and D. Kumar, "Transformers for vision: A survey on innovative methods for computer vision," IEEE Access, 2025, https://doi.org/10.1109/ACCESS.2025.3571735.
D. Li, C. Lu, Z. Chen, J. Guan, J. Zhao, and J. Du, "Graph neural networks in point clouds: A survey," Remote Sens., vol. 16, no. 14, p. 2518, 2024, https://doi.org/10.3390/rs16142518.
S. Soudeep, M. A. Jahin, and M. F. Mridha, "Interpretable dynamic graph neural networks for small occluded object detection and tracking," arXiv preprint arXiv:2411.17251, 2024, https://doi.org/10.48550/arXiv.2411.17251.
C. Chen, Y. Wu, Q. Dai, H. Y. Zhou, M. Xu, S. Yang, and Y. Yu, "A survey on graph neural networks and graph transformers in computer vision: A task-oriented perspective," IEEE Trans. Pattern Anal. Mach. Intell., 2024, https://doi.org/10.1109/TPAMI.2024.3445463.
J. H. Choi, J. W. Pyo, Y. C. An, and T. Y. Kuc, "TOSD: A hierarchical object-centric descriptor integrating shape, color, and topology," Sensors, vol. 25, no. 15, p. 4614, 2025, https://doi.org/10.3390/s25154614.
S. Abba, A. M. Bizi, J. A. Lee, S. Bakouri, and M. L. Crespo, "Real-time object detection, tracking, and monitoring framework for security surveillance systems," Heliyon, vol. 10, no. 15, p. e34922, 2024, https://doi.org/10.1016/j.heliyon.2024.e34922.
S. B. Sukhavasi, S. B. Sukhavasi, K. Elleithy, S. Abuzneid, and A. Elleithy, "CMOS image sensors in surveillance system applications," Sensors, vol. 21, no. 2, p. 488, 2021, https://doi.org/10.3390/s21020488.
X. Zhang, Z. Zhou, and S. Qiu, "Enhancing object detection and tracking with attention mechanisms in computer vision," in Proc. 4th Int. Conf. Comput., Artif. Intell. Control Eng. (CAICE), pp. 774–778, 2025, https://doi.org/10.1145/3727648.3727774.
M. Hasanujjaman, M. Z. Chowdhury, and Y. M. Jang, "Sensor fusion in autonomous vehicle with traffic surveillance camera system: Detection, localization, and AI networking," Sensors, vol. 23, no. 6, p. 3335, 2023, https://doi.org/10.3390/s23063335.
S. Tas, O. Sari, Y. Dalveren, S. Pazar, A. Kara, and M. Derawi, "Deep learning-based vehicle classification for low quality images," Sensors, vol. 22, no. 13, p. 4740, 2022, https://doi.org/10.3390/s22134740.
K. Tan, J. Wu, H. Zhou, Y. Wang, and J. Chen, "Integrating advanced computer vision and AI algorithms for autonomous driving systems," J. Theory Pract. Eng. Sci., vol. 4, no. 1, pp. 41–48, 2024, https://doi.org/10.53469/jtpes.2024.04(01).06.
M. Kong, Y. Guo, O. Alkhazragi, M. Sait, C. H. Kang, T. K. Ng, and B. S. Ooi, "Real-time optical-wireless video surveillance system for high visual-fidelity underwater monitoring," IEEE Photon. J., vol. 14, no. 2, pp. 1–9, 2022, https://doi.org/10.1109/JPHOT.2022.3147844.
V. B. Gurav, A. U. Eyyappadi, and K. R. Parmar, "Autonomous security and surveillance system using deep learning and face tracking," Research Square, 2025, https://doi.org/10.21203/rs.3.rs-6505695/v1.
B. Ahmed, S. R. Naqvi, T. Akram, L. Peng, and F. Almarshad, "A hybrid deep learning-ViT model and a meta-heuristic feature selection algorithm for efficient remote sensing image classification," Int. J. Comput. Intell. Syst., vol. 18, no. 1, p. 122, 2025, https://doi.org/10.1007/s44196-025-00838-z.
A. Alotaibi, C. Chatwin, and P. Birch, "AI-driven UAV system for autonomous vehicle tracking and license plate recognition," Open Eng., vol. 15, no. 1, p. 20240101, 2025, https://doi.org/10.1515/eng-2024-0101.
A. Thomas, J. K. Antony, A. V. Isaac, M. S. Aromal, and S. Verghese, "A novel road attribute detection system for autonomous vehicles using sensor fusion," Int. J. Inf. Technol., vol. 17, no. 1, pp. 161–168, 2025, https://doi.org/10.1007/s41870-024-02255-5.
E. A. Laksana, A. P. W. Wibowo, B. Yustim, U. S. Zulpratita, and D. T. S. Wijaya, "Violation detection on traffic light area based on image classification using dimensionality reduction and deep learning," J. Sci. Transp. Technol., vol. 5, no. 1, pp. 32–39, 2025, https://doi.org/10.58845/jstt.utt.2025.en.5.1.32-39. Q
. Yang and R. Guo, "An unsupervised method for industrial image anomaly detection with vision transformer-based autoencoder," Sensors, vol. 24, no. 8, p. 2440, 2024, https://doi.org/10.3390/s24082440.
W. Ullah, T. Hussain, and S. W. Baik, "Vision transformer attention with multi-reservoir echo state network for anomaly recognition," Inf. Process. Manage., vol. 60, no. 3, p. 103289, 2023, https://doi.org/10.1016/j.ipm.2023.103289.
S. Habeb, M. Salama, and L. A. Elrefaei, "Enhancing video anomaly detection using a transformer spatiotemporal attention unsupervised framework for large datasets," Algorithms, vol. 17, no. 7, p. 286, 2024, https://doi.org/10.3390/a17070286.
X. Li, L. Zhang, B. Zhao, Y. Dong, and X. Lu, "TransCNN: Hybrid CNN and transformer mechanism for surveillance anomaly detection," Eng. Appl. Artif. Intell., vol. 123, p. 106173, 2023, https://doi.org/10.1016/j.engappai.2023.106173.
F. Meng, X. Zhang, Y. Wang, and Z. Liu, "Integrating sensor embeddings with variant transformer graph networks for enhanced anomaly detection in multi-source data," Mathematics, vol. 12, no. 17, p. 2612, 2024, https://doi.org/10.3390/math12172612.
F. Zoghlami, M. A. Aganj, and R. A. Aganj, "ViGLAD: Vision graph neural networks for logical anomaly detection," IEEE Access, vol. 12, pp. 173304–173315, 2024, https://doi.org/10.1109/ACCESS.2024.3502514.
V.-T. Le and Y.-G. Kim, "Attention-based residual autoencoder for video anomaly detection," Appl. Intell., vol. 53, no. 3, pp. 3240–3254, 2023, https://doi.org/10.1007/s10489-022-03613-1.
P. Mishra, R. Verk, D. Fornasier, C. Piciarelli, and G. L. Foresti, "VT-ADL: A vision transformer network for image anomaly detection and localization," arXiv preprint arXiv:2104.10036, 2021, https://doi.org/10.48550/arXiv.2104.10036.
E. Caville, W. W. Lo, S. Layeghy, and M. Portmann, “Anomal-E: A self-supervised network intrusion detection system based on graph neural networks,” Knowledge-based systems, vol. 258, p. 110030, 2020, https://doi.org/10.1016/j.knosys.2022.110030.
J. Li, X. Wang, Y. Zhao, and Z. Zhang, "CVTGAD: Simplified transformer with cross-view attention for unsupervised graph-level anomaly detection," arXiv preprint arXiv:2405.02359, 2024, https://doi.org/10.48550/arXiv.2405.02359.
N. Madan et al., "Self-Supervised Masked Convolutional Transformer Block for Anomaly Detection," in IEEE Transactions on Pattern Analysis and Machine Intelligence, vol. 46, no. 1, pp. 525-542, Jan. 2024, https://doi.org/10.1109/TPAMI.2023.3322604.
P. Bergmann, K. Batzner, M. Fauser, D. Sattlegger, and C. Steger, "The MVTec anomaly detection dataset: A comprehensive real-world dataset for unsupervised anomaly detection," Int. J. Comput. Vis., vol. 129, no. 4, pp. 1038–1059, 2021, https://doi.org/10.1007/s11263-020-01400-4.
Y. Zou, J. Jeong, L. Pemula, D. Zhang, and O. Dabeer, “Spot-the-difference self-supervised pre-training for anomaly detection and segmentation,” In European conference on computer vision, pp. 392-408, 2022, https://doi.org/10.1007/978-3-031-20056-4_23.
A. Dosovitskiy et al., “ An image is worth 16x16 words: Transformers for image recognition at scale. arXiv preprint arXiv:2010.11929, 2021, https://doi.org/10.48550/arXiv.2010.11929.
A. Radford, J. W. Kim, C. Hallacy, A. Ramesh, G. Goh, S. Agarwal, G. Sastry, A. Askell, P. Mishkin, J. Clark, G. Krueger, and I. Sutskever, "Learning transferable visual models from natural language supervision," arXiv preprint arXiv:2103.00020, 2021, https://doi.org/10.48550/arXiv.2103.00020.
Z. Liu et al., "Swin Transformer: Hierarchical Vision Transformer using Shifted Windows," 2021 IEEE/CVF International Conference on Computer Vision (ICCV), pp. 9992-10002, 2021, https://doi.org/10.1109/ICCV48922.2021.00986.
W. Wang, X. Zhang, Y. Wang, Z. Liu, and F. Meng, "N-STGAT: Spatio-temporal graph neural network for intrusion detection," Remote Sens., vol. 15, no. 14, p. 3611, 2023, https://doi.org/10.3390/rs15143611.
A. A. M. Fatima, "A generative pattern extraction algorithm tackling ultra-imbalanced data in financial fraud detection systems," PatternIQ Min. (PIQM), vol. 2, no. 4, pp. 19–41, 2025, https://doi.org/10.70023/sahd/242502.
A. G. Jaber, A. A. Ali, A. A. Mahmood, M. J. Salim, G. J. Mohammed, and K. A. Z. Ariffin, "Dynamic quantization-aware neural architecture search for real-time encrypted traffic classification in 5G networks," Al-Iraqia J. Sci. Eng. Res., vol. 5, no. 1, pp. 34–48, 2026, https://doi.org/10.58564/IJSER.5.1.2026.365.
L. Wen et al., “UA-DETRAC: A new benchmark and protocol for multi-object detection and tracking,” Computer Vision and Image Understanding, vol. 193, p. 102907, 2020, https://doi.org/10.1016/j.cviu.2020.102907.
Published
How to Cite
Issue
Section
License
Copyright (c) 2026 Abeer Ahmed Ali, Abdullah Ghanim Jaber, Ali A. Mahmood, Mohammed Jamal Salim

This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License.
Authors who publish with this journal agree to the following terms:
- Authors retain copyright and grant the journal right of first publication with the work simultaneously licensed under a Creative Commons Attribution License that allows others to share the work with an acknowledgment of the work's authorship and initial publication in this journal.
- Authors are able to enter into separate, additional contractual arrangements for the non-exclusive distribution of the journal's published version of the work (e.g., post it to an institutional repository or publish it in a book), with an acknowledgment of its initial publication in this journal.
- Authors are permitted and encouraged to post their work online (e.g., in institutional repositories or on their website) prior to and during the submission process, as it can lead to productive exchanges, as well as earlier and greater citation of published work (See The Effect of Open Access).

This journal is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License.